For decision-makers
One value per period, with interval and change: it reads well in a meeting and stands up to questions.
AI Trust Score
Six signals observed in AI assistants’ answers, in one value from 0 to 100: how often they name you, recommend you, cite your sources, speak well of you, prefer you to competitors and stay consistent. Code calculates it, never a model.
Why a number
Before choosing, a customer can ask ChatGPT, Gemini, Perplexity, Copilot or Claude and read a ready-made answer. Mentions, recommendations, sources, tone and competitors move together: following them one by one is slow, presenting them to decision-makers is hard.
The score gives the team a shared reference, with a published method and the details always one click away. It does not replace the measures: it orders them and shows which signal to work on first.

One value per period, with interval and change: it reads well in a meeting and stands up to questions.
The dimensions that weigh most and those that hold back, with the answers behind them.
The cited sources and the statements to clarify, linked to Actions.
The six dimensions
Each dimension is a ratio of observed counts, from 0 to 100, with its own sample. The weights add up to 100 and change only with a new, published version of the method.
Authority in version 1 measures the presence of your sources among those cited; the quality of the source type will come with a later version. Preference compares mentions in pairs: 50 means parity, whatever the number of competitors.
| Dimension and weight | What it observes | On what base |
|---|---|---|
| Visibility · 25% | How often answers name you. | Complete, reviewed answers, averaged by question and assistant. |
| Recommendations · 20% | How often they recommend you for the need in the question. | The same answers as Visibility. |
| Authority · 15% | How much the answers that show sources cite your pages. | Only answers in which the citation can be assessed. |
| Reputation · 15% | The tone of the answers when they name you. | Positive, neutral (counted as half) and negative mentions. |
| Preference · 15% | Where you stand against each declared competitor. | Pairwise comparisons in the same answers. |
| Consistency · 10% | How stable your presence stays across assistants and runs. | Only where you appear: absence is already in Visibility. |
How it is calculated
The language model reads an answer and classifies it: does it name the brand, recommend it, cite one of its pages, with what tone, next to which competitors. A deterministic judge checks every classification against the text and a person reviews it. The score is calculated by code, from those counts only.
The total is the sum of weight times value for the measured dimensions, divided by the sum of their weights. Same data, same result, on every machine.
The same questions, to the same assistants, in every cycle.
An extractor classifies, a deterministic judge checks, a person reviews.
Each dimension with its numerator, its denominator and its weight.
A weighted average, always shown with coverage and a 95% interval.
Sample and coverage
A dimension is measured only with enough observations. Below the threshold it stays excluded and declared, with the reason: it is not worth zero and does not quietly lower the total.
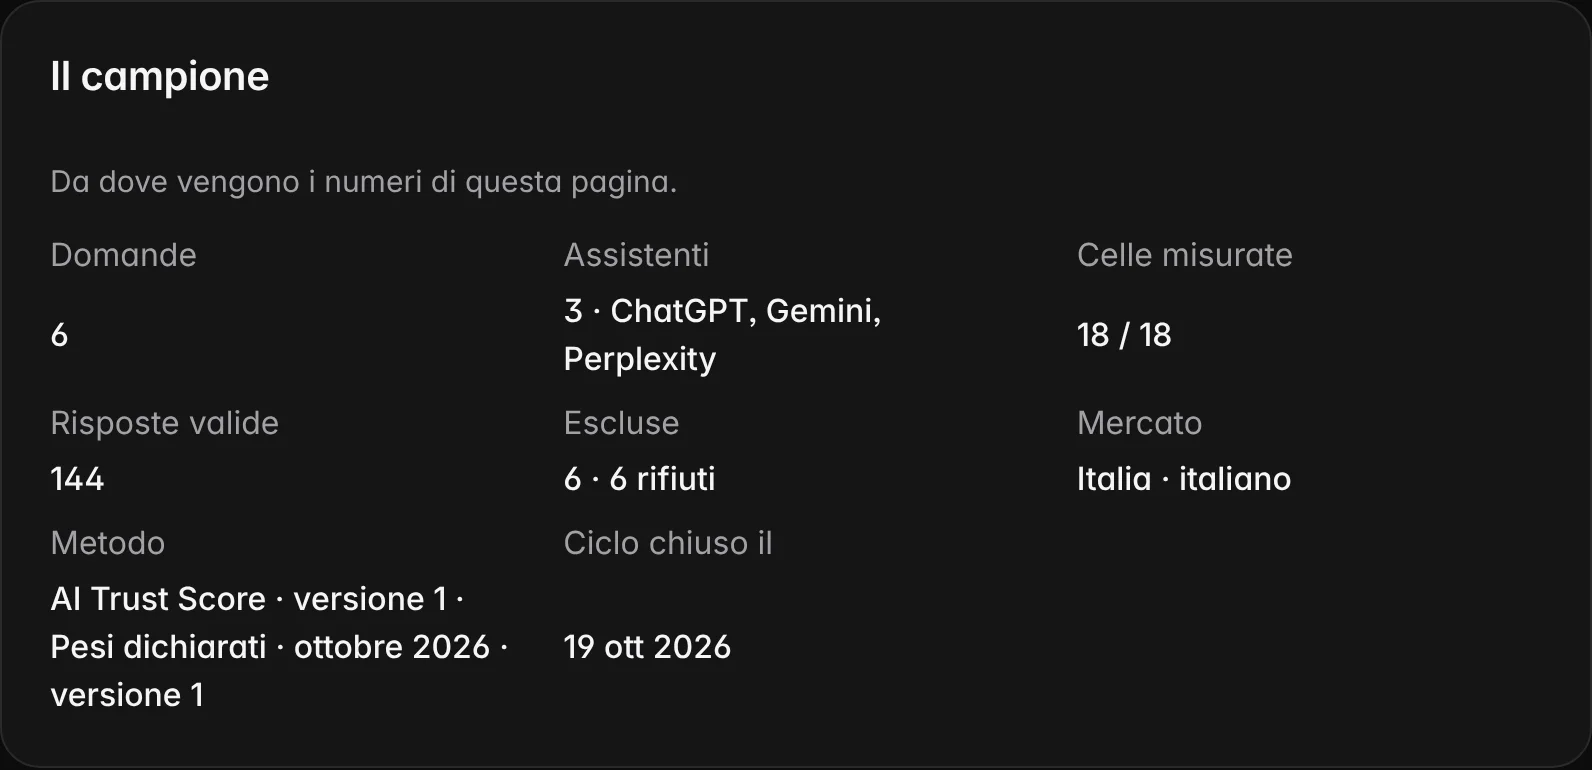
For each dimension, plus a minimum of questions or competitors: a single case does not decide a value.
The sum of the measured weights. The total appears only if Visibility is measured and coverage reaches at least 70%.
Next to the value, the range the total would have if the excluded dimensions were worth 0 or 100.
Uncertainty
A score without an interval promises a precision the sample does not have. That is why the 95% credible interval always appears next to the value, with the declared precision.
The interval comes from 10,000 Monte Carlo draws with a fixed seed, resampling questions and assistants: the same panel always gives the same interval. If the half-width exceeds 15 points, the value is declared “beyond the precision threshold”.
The same sample value with two different samples: the narrow interval is compared, the wide one is declared as beyond the 15-point threshold set by the method.
| Made-up example | Value and 95% interval | How to read it |
|---|---|---|
| Large panel | 62, between 58 and 66: half-width of 4 points. | Precision within the threshold: the value enters comparisons. |
| Reduced panel | 62, between 44 and 80: half-width of 18 points. | Beyond the 15-point threshold: the value is published and declared as such. |
| Same panel, again | The same interval, at every new calculation. | The fixed seed makes the Monte Carlo draws repeatable. |
Comparisons over time
Every score carries the fingerprint of the method that produced it: version, weights, thresholds, statistics. Two values line up only with the same fingerprint; a method change breaks the series instead of inventing a change.
The comparison says how much the score changed. Attributing an effect requires experiments with a control group.
The same calculation on a single assistant’s answers: smaller bases, wider intervals, declared.
Competitors’ six dimensions on the same questions, where the data allow.
From number to action
The dimensions that contribute most and those that weigh least are read in points, with their base. From there you open the answer behind them and prepare the right action: a page to clarify, a source to win, an FAQ to write.
A sample reading for a fictional brand: the dimension that supports the score, the one that holds it back, the answer to open and the action that follows.
What it is not
It is a proprietary indicator with a published method. It summarises what the observed answers say about you, over one period, for one market and one language.
It observes answers; nobody measures what a model “thinks”.
Nor a sales forecast, nor a rating of its products.
No value comes from a language model: only reviewed counts.
Frequently asked questions
Why the AI Trust Score uses six dimensions, what it really measures, why a dimension can be missing and how it differs from the Visibility Index.
Because being named, being recommended, being cited as a source, tone, comparison with competitors and stability change for different reasons. The value from 0 to 100 summarises them, and each one stays readable with its own base.
No. Nobody can measure what a model “thinks”. The score summarises signals observable in answers: mentions, recommendations, sources, tone, comparisons and stability.
No. You can work on content and sources and measure what changes, with the same method. Nobody can promise an increase.
Because it did not reach the minimum sample. It stays excluded and declared; if coverage drops below 70% of the weights, the total is not calculated.
The Visibility index summarises presence across five channels: AI, search, social, press and reputation. The AI Trust Score looks only at AI answers and reads six dimensions in them. They are two distinct methods, published separately.
Those in your panel, qualified for the period and declared next to the value. Every combination of question and assistant carries the same weight.
Related paths
Each feature answers a specific question. From here you move on to related features, to the methodology behind their measures and to help for using them in everyday work.
AI visibility, AI Trust Score, search, reputation, competitors, actions and execution: a feature for every question about your brand.
ReadHow TrustInsider works in six steps: brand, questions, quote, evidence, page-by-page intervention and a check on the same questions.
ReadHow every TrustInsider measure is built: sampling of AI answers, sources and rights, index calculation and declared limits.
ReadHelp with access, credits, collections, integrations and data: guides, FAQs, the site assistant and support requests from your workspace.
Read